Preparing for Traffic: How to Scale Your Infrastructure
Part 2 of 5 in the System Design Series
In 2018, Ticketmaster sold tickets to a Taylor Swift tour. Millions of fans refreshed the page simultaneously. The site slowed to a crawl. Some couldn't get through at all.
This wasn't a bug. It was a scaling failure. And it's the kind of problem that can take down even well-funded systems in minutes.
Let's talk about what happens when your server can no longer keep up, and what engineers actually do about it.
The Single Server Problem
When you first launch an app, everything lives on one server. One machine handling every request, every database query, every user session. For a few hundred users, this is perfectly fine.
Then your app gets traction. More users. More requests. The server starts struggling, response times slow down, errors creep in, and eventually the whole thing crashes under the weight.
At this point, you have a decision to make.
Option 1: Vertical Scaling (Scaling Up)
The intuitive first move is to upgrade the machine you already have. More CPU. More RAM. Faster storage. This is called vertical scaling, making the one thing you have bigger and more powerful.
It works. And it's simple, no code changes, no architectural rethinking, just upgrade and move on.
But there's a ceiling. You can only make a single machine so powerful before you hit the physical limits of what hardware can do, and the cost grows exponentially as you approach those limits. A server with 64GB of RAM doesn't cost twice as much as one with 32GB. It often costs four times as much.
The deeper problem, though, is reliability. If your entire application lives on a single machine and that machine goes down, a hardware fault, a power failure, a bad software deployment, your entire application goes down with it. One point of failure for everything.
That's not a foundation you want to build a real business on.
Option 2: Horizontal Scaling (Scaling Out)
The more robust solution is horizontal scaling, instead of making one machine bigger, you add more machines and spread the work across all of them.
Picture a restaurant kitchen. When orders pile up, you don't buy one chef a bigger stove. You hire more chefs. Each one handles a portion of the tickets, and together they keep pace with demand.
Horizontal scaling works the same way. If one server fails, the others continue serving users without interruption. If traffic spikes, you spin up more servers to absorb the load. When things quiet down, you scale back.
This is the architecture behind every major tech company. Netflix, Twitter, Uber, they're not running on one powerful server. They're running on thousands of relatively modest ones.
The New Problem: Who Decides Which Server?
Here's the catch. Once you have multiple servers, you have a coordination problem.
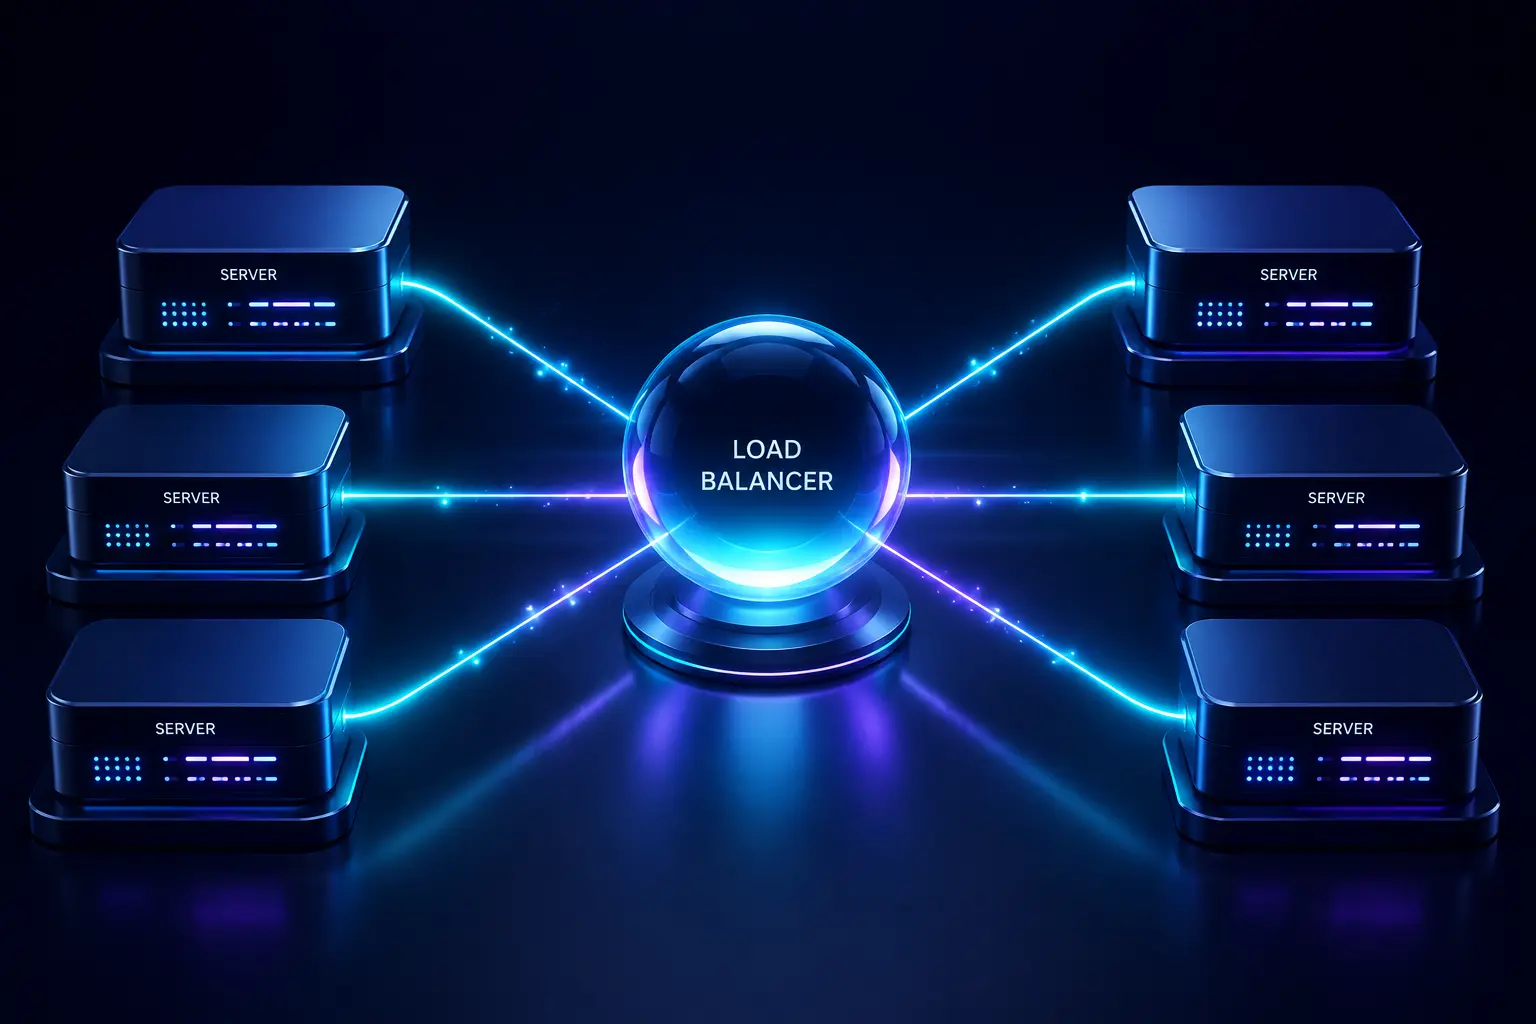
A user's request arrives. Which server handles it? If all requests go to server 1, servers 2 and 3 sit idle while server 1 gets overwhelmed. That defeats the entire purpose.
This is where a load balancer comes in.
The load balancer sits in front of your servers like a traffic controller at a busy intersection. Every incoming request passes through it, and it decides, based on a set of rules, which server should handle it.
Two common approaches:
- Round-robin, Requests are distributed evenly in rotation. Request 1 goes to Server A, request 2 to Server B, request 3 to Server C, then back to Server A. Simple and effective for uniform traffic.
- Least connections, The load balancer sends each new request to whichever server currently has the fewest active connections. Better for situations where some requests are heavier than others.
What This Looks Like in Practice
Think back to those Taylor Swift ticket sales. The root cause wasn't that Ticketmaster's servers were weak. It was that the system wasn't designed to handle a sudden, massive spike in concurrent users.
A properly scaled system for that moment would have looked something like this:
- A load balancer at the front, routing tens of thousands of simultaneous requests
- Dozens (or hundreds) of horizontally scaled server instances absorbing the load
- The ability to spin up new servers automatically as traffic surged
Scaling the compute layer solves one half of the problem. The other half is the data. In Part 3, we'll look at how databases handle scale, and why a single database can become your biggest bottleneck.
Previous: Part 1 → How Computers Talk Next: Part 3 → Managing the Data: Databases and Optimisation Techniques